Indexing job
Introduction
This page describes content indexing jobs in Backup Administration for Microsoft 365. Content indexing jobs assign the default index zone to files, emails, Teams messages, and Teams chat messages from the selected entities, making the content searchable in the contentACCESS Portal.
The indexing jobs use Elasticsearch as the backend server to manage and store indexes and perform searches. They also crawl Backup Administration and send document text and metadata to the Elasticsearch server.
The following sections cover how to configure an indexing job, including its name, cluster nodes, schedule, index zone, entities to index, filtering, notification, and resource settings, as well as how to save and run an indexing job and monitor its progress on the Job progress page.
Note: Document text is extracted from various document formats through IFilter components. The appropriate IFilter pack should be installed on the server where Backup Administration for Microsoft 365 is also installed. These filters are used to extract plain text content from binary formats such as .docx, .pdf, and other supported formats.
Indexing job configuration
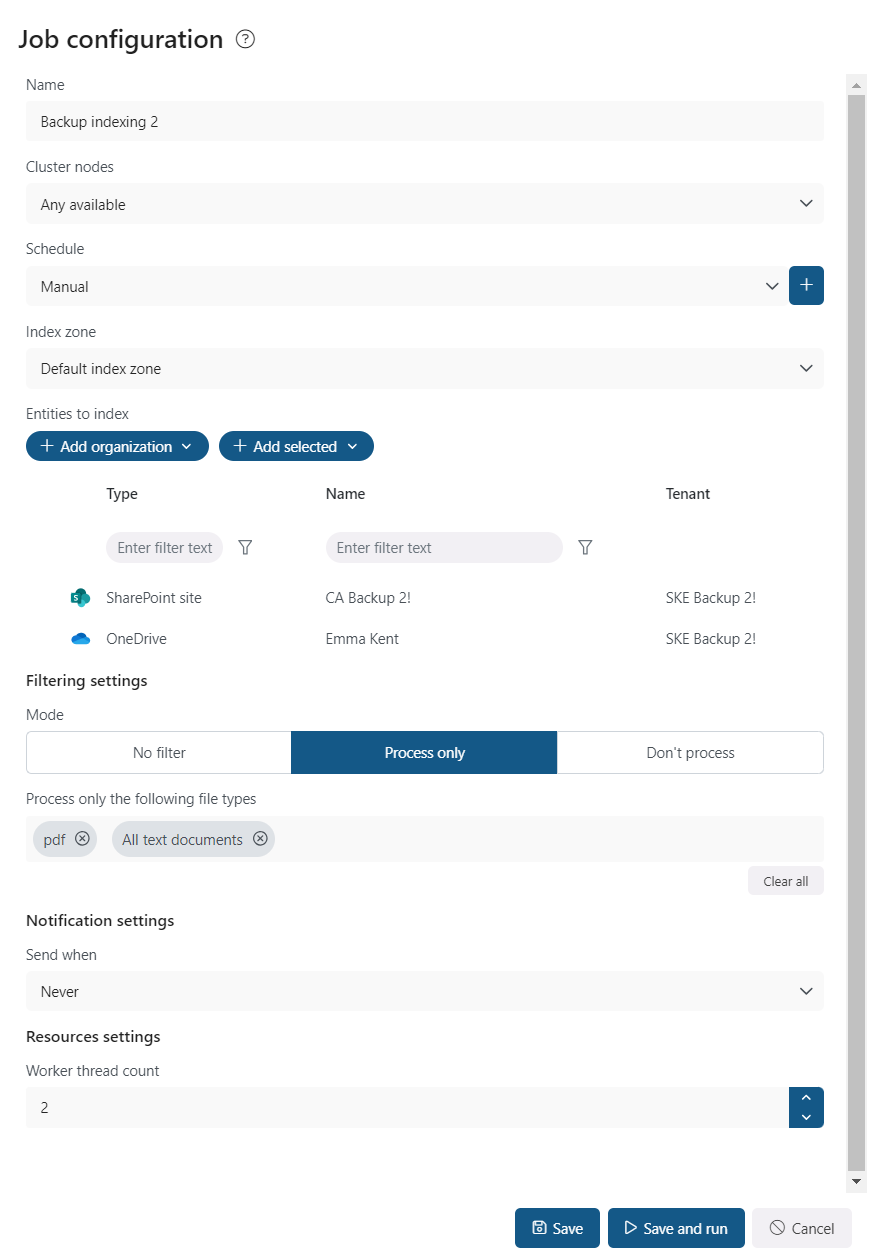
On the Job configuration page, configure the following sections:
- Name: Each indexing job requires a unique name to distinguish it from other indexing jobs. It is recommended to use a name that clearly indicates the purpose of the job. By default, the automatically created indexing job is called Backup indexing.
- Cluster nodes: Select the node where the indexing job will run.
- Schedule: Select the running times of the indexing job. You can either select an existing schedule from the list or create a new one by clicking the + button in the Schedule row. For indexing jobs, it is recommended to set up a schedule that runs continuously or at specific times during the week. For more information about configuring schedules, see Schedules.
- Index zone: Select the index zone to be assigned to items by the indexing job. Currently, only the default index zone is available; it is not possible to create a new index zone manually.
- Entities to index: Select the entities to be processed by the indexing job. See the Entities to index section below for details.
- Filtering settings: Define which file types should or should not be processed. See the Filtering settings section below for details.
- Notification settings: Configure when the indexing job should send notification emails. You can choose to receive notifications always, never, or only when an error or warning occurs — for example, when indexing fails for one or more items. Enter the recipient email addresses in the Recipient list textbox.
- Resource settings: Set the value that determines how many items can be processed simultaneously by the indexing job. The recommended value is 2.
Entities to index
There are two options to choose from:
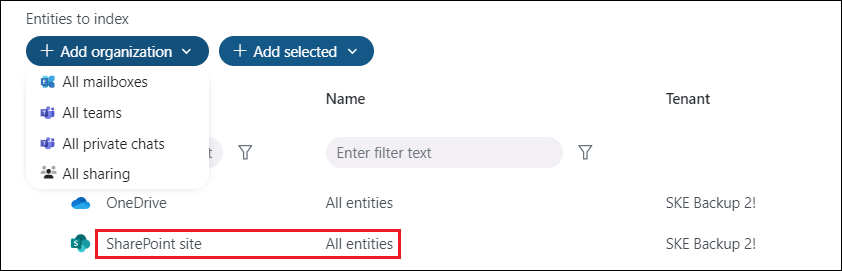
- + Add organization: Processes all mailboxes, SharePoint or OneDrive sites, teams, or private chats.
- + Add selected: Processes only the selected entities.
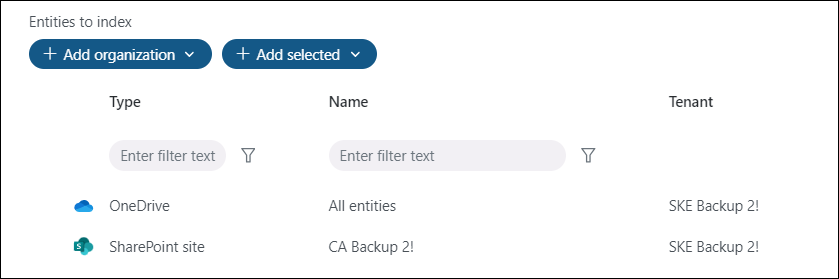
If you choose + Add organization, all entities of the selected type are listed in the Entities to index section.
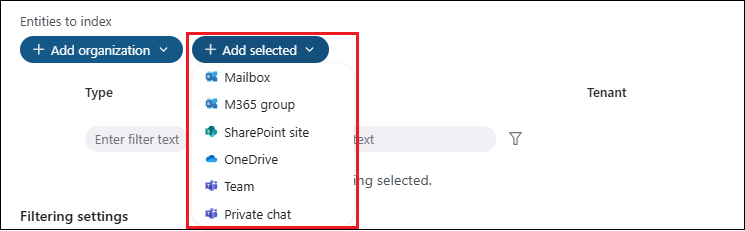
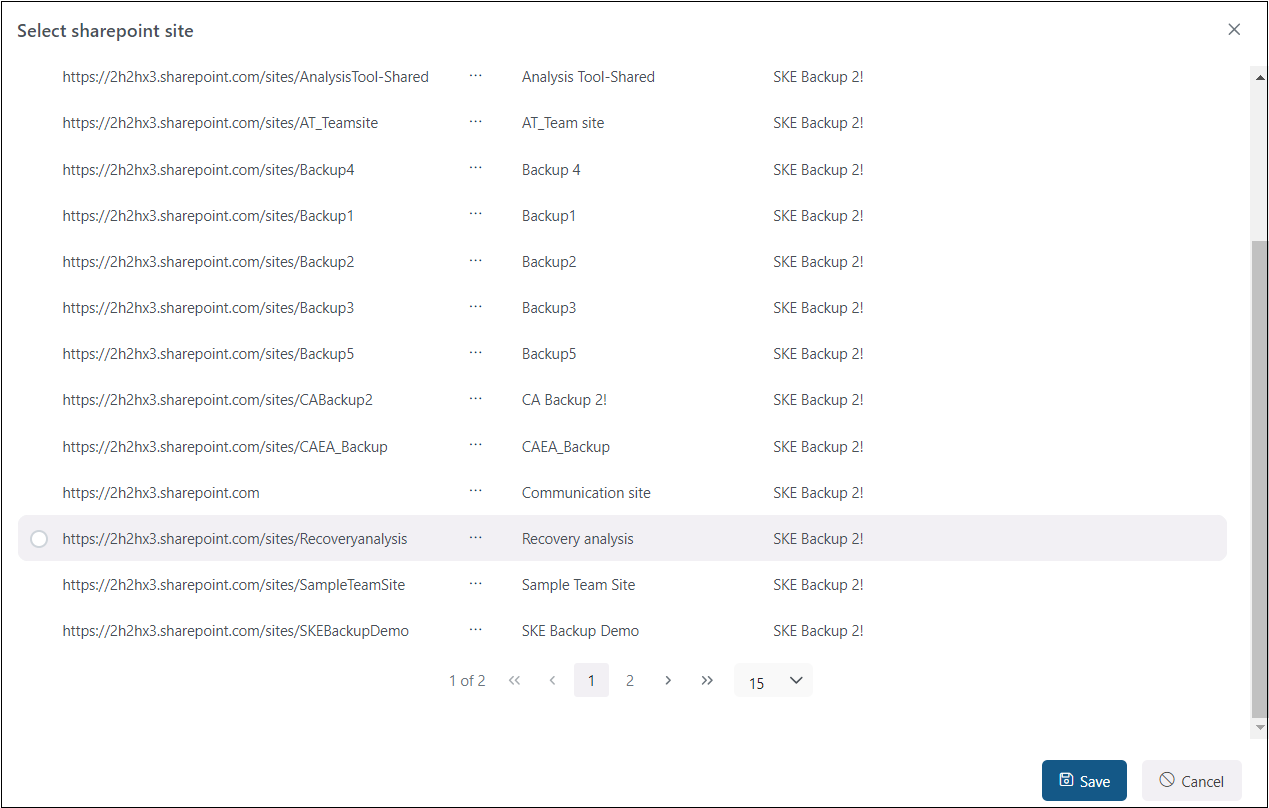
To index only selected entities, click + Add selected and choose the required items from the dropdown menu. A repository of entities opens in a pop-up window — select the desired entities and click Save.
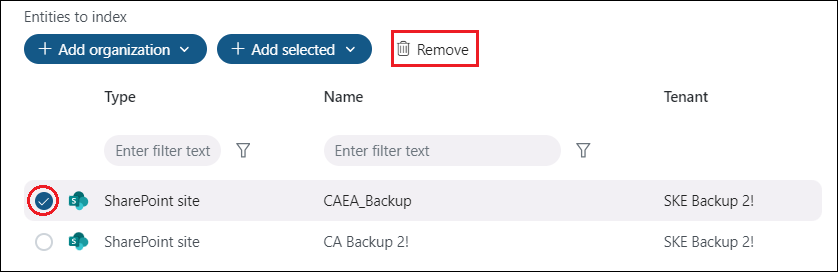
You can remove previously selected entities by selecting them from the list. A Remove option will appear in the Entities to index section.
Note: You can select multiple entities from different modules at once. For example, indexing can run on both mailboxes and teams simultaneously with the same indexing job.
Filtering settings
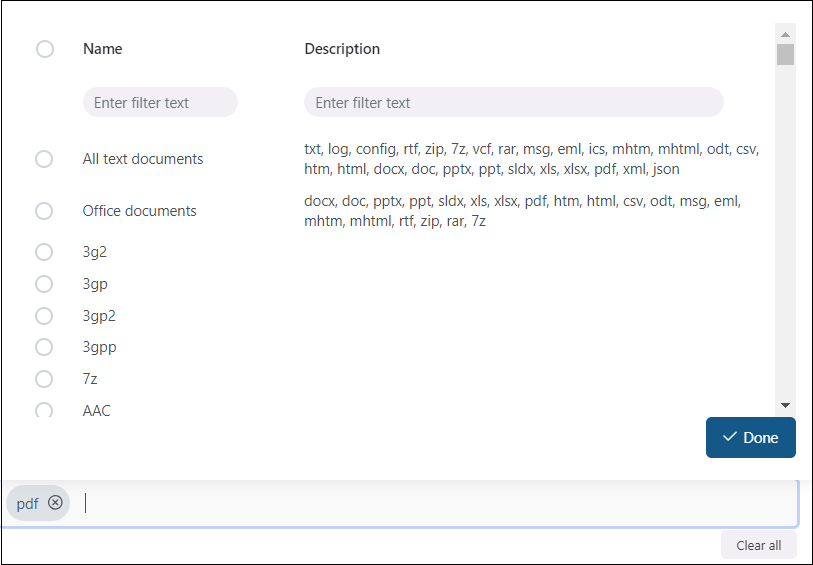
In this section, you can define which file types should or should not be processed, or run the indexing job without applying any filters. File types can be added individually, or selected from predefined groups:
- All text documents – contains extensions such as
txt,log,config,rtf,zip,7z,eml,json, andmhtm. - Office documents – contains extensions such as
docx,pptx,xlsx,pdf, andhtml.
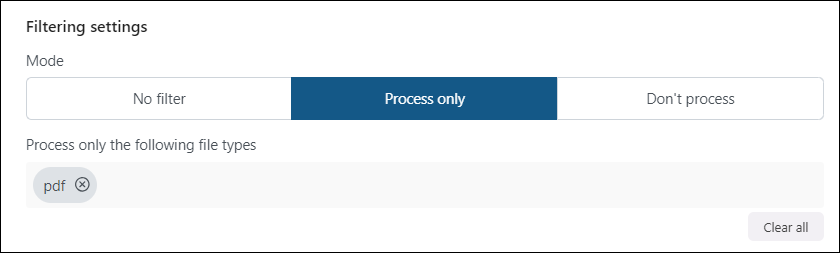
The indexing job can run in three modes:
- No filter – processes all items from the selected entities.
- Process only – processes only items matching the specified file types.
- Don't process – excludes items with the specified file extensions.
The advanced filtering option is available in both Process only and Don't process modes. Click the Process only the following file types textbox to open a pop-up window with available groups and individual extensions. Multiple file types and groups can be selected at once. Extensions can be found using the search bar, by scrolling through the list, or by entering them manually in the textbox.
Save and run the indexing job
After configuring the indexing job, click Save at the bottom of the page to save the configuration and return to the Jobs page. If you want to start processing immediately, click Save and run — the indexing job starts and you are redirected to the Job progress page.
Monitor indexing progress
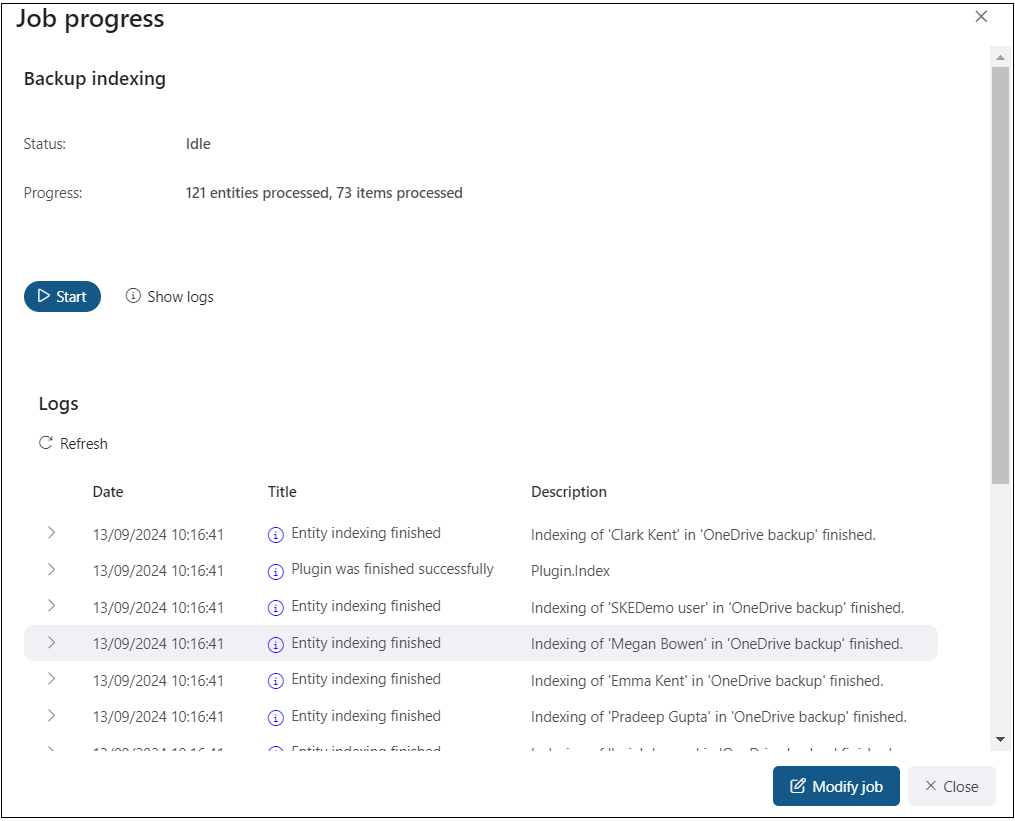
On the Job progress page, you can monitor the indexing job and check its current status and progress. You can also:
- restart a finished job or stop a running job using the Start/Stop button;
- view the latest logs by clicking Show last logs;
- view the session logs of the currently running job; and
- modify the job by clicking Modify job, which redirects you to the Job configuration page.